Machine learning models allow computers to recognise patterns in data and use those patterns to make predictions or decisions. They support applications such as spam detection, product recommendations, fraud monitoring, medical image analysis, and demand forecasting. Understanding machine learning models begins with two questions: how do they learn from data, and what type of problem must they solve?
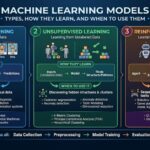
The main learning approaches are supervised learning, unsupervised learning, semi-supervised learning, and reinforcement learning. Each approach uses data differently. Supervised learning learns from examples with known answers, while unsupervised learning searches for patterns without predefined labels. Semi-supervised learning combines labelled and unlabelled examples, and reinforcement learning learns through actions and feedback from an environment.
These categories are useful, but they do not describe every aspect of a model. A classification model, for example, might use logistic regression, a decision tree, or a neural network. Those algorithms can differ significantly in accuracy, interpretability, training cost, and performance on new data.
Choosing the right approach therefore requires more than selecting a popular algorithm. Developers must consider the intended outcome, the reliability of available data, the consequences of incorrect predictions, and the practical demands of running the system.
This guide explains the main learning categories, compares commonly used algorithms, and examines the trade-offs that influence real-world machine learning projects. It also outlines how to evaluate models and what developments may shape their use in 2027.
Main Types of Machine Learning Models
The four main learning approaches describe how a system receives information and improves its performance.
1. Supervised Learning
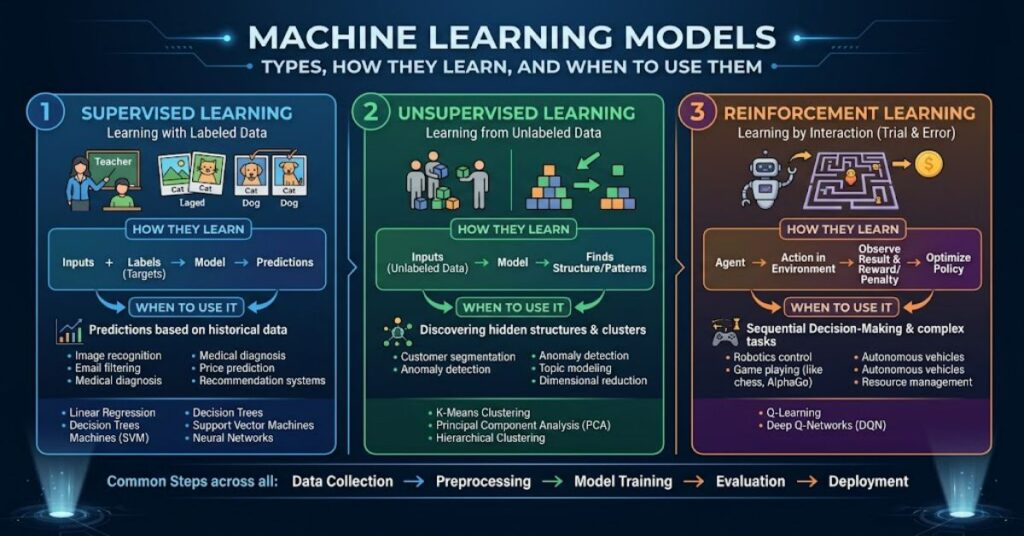
Supervised learning uses labelled examples, where each training record contains input data and a known target. The model learns a relationship between the two and applies it to unseen examples.
For instance, a bank might train a model on historical transactions labelled as fraudulent or legitimate. The model can then estimate whether a new transaction is suspicious.
Common tasks include classification and regression. Classification predicts categories, while regression estimates numerical values.
Typical algorithms include linear regression, logistic regression, decision trees, random forests, and support vector machines. Neural networks can also perform supervised tasks.
2. Unsupervised Learning
Unsupervised learning works with data that lacks predefined target labels. Instead of learning known answers, the algorithm identifies patterns, similarities, clusters, or unusual observations.
A retailer might use clustering to group customers according to purchasing behaviour. These groups can inform product recommendations, marketing campaigns, or stock planning.
Common techniques include K-means clustering, hierarchical clustering, principal component analysis (PCA), and anomaly detection methods.
The main limitation is interpretation. A cluster may reveal a mathematical pattern without explaining why that pattern exists or whether it has practical value.
3. Semi-Supervised Learning
Semi-supervised learning combines a smaller collection of labelled examples with a larger collection of unlabelled data. It can be useful when collecting raw data is easy but assigning accurate labels requires specialist time.
For example, a healthcare organisation might have thousands of medical images but only a limited number reviewed and labelled by qualified clinicians.
This approach can reduce labelling demands, although poor-quality labels or unsuitable assumptions about the unlabelled data can undermine performance.
4. Reinforcement Learning
Reinforcement learning trains an agent to choose actions within an environment. The agent receives rewards or penalties and learns a policy intended to maximise cumulative reward.
Applications include robotics, simulated control systems, resource allocation, and some game-playing systems.
Its effectiveness depends on the quality of the reward function and the environment used for training. A poorly designed reward can encourage behaviour that technically meets the target but fails to meet the real objective.
Comparison of Learning Approaches
| Approach | Data requirement | Main purpose | Example |
| Supervised | Labelled examples | Predict known outcomes | Spam classification |
| Unsupervised | Unlabelled examples | Discover patterns | Customer segmentation |
| Semi-supervised | Some labelled and many unlabelled examples | Improve learning with fewer labels | Image classification |
| Reinforcement | Actions, states and rewards | Learn a sequence of decisions | Robot navigation |
These categories can overlap with broader techniques. Deep learning, for example, is not a separate learning category in the same sense. It uses multilayer neural networks and can be applied to supervised, unsupervised, self-supervised, and reinforcement learning tasks.
Common Algorithms and Their Practical Uses
The learning approach determines how training works, while the algorithm determines how the model represents patterns and produces outputs.
| Algorithm | Common use | Main advantage | Main limitation |
| Linear regression | Numerical forecasting | Simple and interpretable | Limited for complex relationships |
| Logistic regression | Classification | Efficient baseline with useful probability estimates | May miss complex patterns |
| Decision tree | Classification and regression | Rules are relatively easy to explain | Can overfit |
| Random forest | Classification and regression | Handles varied patterns effectively | Less transparent than a small tree |
| K-means | Clustering | Straightforward segmentation | Requires choosing the number of clusters |
| Support vector machine | Classification | Effective in some high-dimensional datasets | Scaling can be difficult for large datasets |
| Neural network | Images, text and complex signals | Learns complex representations | May require substantial data and computing |
There is no universally best algorithm. A simple model can outperform a more complex alternative when the dataset is small, the signal is straightforward, or interpretability is important.
How to Choose the Right Model
Begin with the outcome rather than the technology. If the goal is to predict house prices, regression is a natural starting point. If the goal is to identify fraudulent transactions, classification may be appropriate. If customer groups are unknown, clustering may be more useful.
Next, inspect the data. Missing values, inconsistent labels, duplicated records, and unrepresentative samples can distort results. Data preparation should also prevent leakage, which occurs when information unavailable at prediction time influences training.
Choose an evaluation metric that reflects the real cost of errors. Accuracy may be misleading when one category dominates the dataset. In fraud detection, for example, precision measures how many flagged transactions are actually fraudulent, while recall measures how many fraudulent transactions the model identifies.
Finally, compare a simple baseline with more advanced candidates. The additional complexity is justified only when it provides a meaningful improvement that can be maintained in production.
Evaluating Performance and Avoiding Common Errors
Training a model is only one stage of development. A model can perform well on familiar examples but fail when it encounters new data, a problem known as overfitting.
A standard workflow separates data into three sets:
- Training data teaches the model.
- Validation data helps select algorithms and tune settings.
- Test data provides a final assessment on examples not used during model development.
Google’s Machine Learning Crash Course recommends independent testing and representative datasets. Duplicate records or differences between test data and real-world conditions can make performance appear stronger than it is. (Google for Developers, Machine Learning Crash Course.)
The following table summarises useful evaluation measures.
| Problem | Useful metric | What it measures |
| Classification | Accuracy | Overall proportion of correct predictions |
| Classification | Precision | Reliability of positive predictions |
| Classification | Recall | Proportion of actual positives identified |
| Regression | Mean absolute error | Average absolute prediction error |
| Regression | Root mean squared error | Prediction error with greater emphasis on large errors |
| Clustering | Silhouette score | How well observations fit their assigned clusters |
No single metric captures every aspect of performance. A fraud detection system may need high recall, while an automated system that blocks legitimate payments may place greater weight on precision. Evaluation should reflect the consequences of both false positives and false negatives. (Scikit-learn, Model Selection and Evaluation.)
Risks and Real-World Limitations
Three issues deserve particular attention when developing predictive systems.
First, better test scores do not guarantee better real-world results. Historical data may not represent future customers, market conditions, or unusual events. Monitoring for data drift can help identify when incoming information changes.
Second, a model can reproduce existing bias. If historical decisions reflect unequal treatment, a model trained on those decisions may preserve that pattern. Teams should assess performance across relevant groups, document limitations, and provide human review where mistakes could cause harm.
Third, deployment costs can outweigh small performance gains. A complex neural network may require more computing power, specialist knowledge, and monitoring than a simpler model. For a small organisation, a transparent algorithm that performs reliably may provide greater overall value.
The National Institute of Standards and Technology’s AI Risk Management Framework, released on 26 January 2023, provides guidance for managing AI risks throughout development, deployment, and use. It emphasises reliability, transparency, accountability, security, and fairness. These considerations belong in the development process, not just in a final compliance review.
The Future of Machine Learning Models in 2027
By 2027, machine learning development is likely to place continued emphasis on foundation models, smaller specialised models, automated evaluation, and deployment on devices with limited computing resources. These directions build on existing technical developments, but their adoption will vary by sector and budget.
Self-supervised learning, which derives training signals from unlabelled data, is already important in language and image systems. It can reduce dependence on manually labelled examples, although high-quality training data and task-specific evaluation remain essential.
Another likely priority is operational governance. Organisations will need clearer processes for documenting model behaviour, tracking changes in performance, protecting sensitive information, and investigating errors. The NIST framework and its associated guidance provide a basis for this work, although they do not guarantee that a system will be safe or accurate.
The practical direction is clear: organisations should assess models on measurable outcomes, maintain appropriate human oversight, and choose technology that fits the problem rather than adopting complexity for its own sake. The exact pace of these changes remains uncertain.
Key Takeaways
- Select the learning approach according to the task and the data available.
- Establish a simple baseline before investing in complex architectures.
- Use independent test data to measure generalisation.
- Choose metrics that reflect the real cost of incorrect predictions.
- Review data quality, privacy, and bias before deployment.
- Monitor models after launch because real-world conditions change.
- Balance predictive performance against operating costs and interpretability.
Conclusion
Machine learning models provide a practical way to turn data into predictions, classifications, recommendations, and decisions. Their effectiveness depends on the relationship between the learning approach, the algorithm, the available data, and the problem being solved.
Supervised learning is useful when known outcomes are available. Unsupervised learning helps uncover patterns, while semi-supervised learning can make use of limited labels. Reinforcement learning supports decisions that develop through interaction and feedback.
However, selecting an algorithm is only the beginning. Strong projects require careful data preparation, suitable evaluation metrics, independent testing, and ongoing monitoring. They must also account for bias, privacy, interpretability, and the cost of operating a system.
As machine learning continues to develop towards 2027, dependable evaluation and responsible deployment will remain as important as technical innovation. A well-chosen, carefully maintained model is often more valuable than a sophisticated system whose limitations are poorly understood.
Frequently Asked Questions
1. What are machine learning models?
Machine learning models are computational systems trained on data to identify patterns and produce predictions or decisions. They can classify information, estimate numerical values, group similar records, or select actions.
2. What are the four main types of machine learning?
The four commonly taught approaches are supervised learning, unsupervised learning, semi-supervised learning, and reinforcement learning. They differ in how training information is provided and how the system improves.
3. Which machine learning model is best for beginners?
Linear regression and decision trees are useful starting points because their behaviour is relatively easy to understand. Logistic regression is another good option for basic classification tasks.
4. What is the difference between deep learning and machine learning?
Deep learning is a branch of machine learning that uses neural networks with multiple layers. Traditional machine learning also includes methods such as linear regression, decision trees, and support vector machines.
5. Can machine learning models make mistakes?
Yes. Models can fail because of poor data, bias, overfitting, changing conditions, or unfamiliar examples. Independent testing and ongoing monitoring help identify these problems.
6. How are machine learning models evaluated?
Evaluation uses separate data and suitable metrics, such as precision, recall, accuracy, mean absolute error, or clustering measures. The correct metric depends on the task and the cost of mistakes.
Methodology
This article draws on established technical documentation from Google for Developers, Scikit-learn, and the US National Institute of Standards and Technology. These sources support the explanations of dataset splitting, model evaluation, and responsible AI development.
The comparison tables summarise common applications and limitations rather than reporting results from a new benchmark. No independent model testing or expert interviews were conducted for this article. Algorithm performance varies with dataset characteristics, implementation, and evaluation design, so readers should validate any model against their own requirements.
References
- Google for Developers. Machine Learning Crash Course: Dividing the Original Dataset. Updated 2025.
- National Institute of Standards and Technology. Artificial Intelligence Risk Management Framework (AI RMF 1.0). 2023.
- Scikit-learn Developers. Model Selection and Evaluation. Scikit-learn documentation.
- Scikit-learn Developers. Metrics and Scoring. Scikit-learn documentation.